The Cost of an Ambiguous Entity
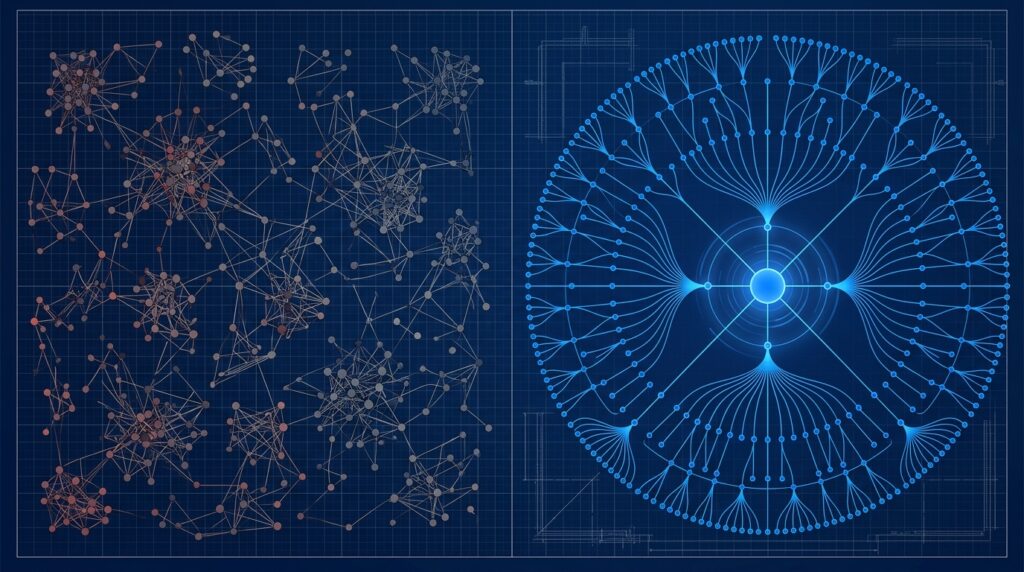
A generative engine does not rank your homepage. It retrieves a passage, checks whether that passage can be attributed to a verifiable entity, and decides whether citing you carries reputational risk for the model. That attribution step depends on structured data resolving to one consistent answer: who is this organisation, what is this website, how do they relate. When a page emits two Organization declarations with different names, or a WebSite node that contradicts the Organization node it should be pointing to, the model has no reliable way to determine which declaration is authoritative. It does not average them. It does not pick the more recent one. In most observed retrieval behaviour, it discards the structured data layer entirely and falls back to unstructured text — or it skips the page as a citation candidate altogether.
This is the mechanism behind what we call schema debt: the accumulation, over successive plugin installs, theme updates and migrations, of multiple JSON-LD blocks on the same URL that were never designed to coexist. Each block was correct in isolation, at the moment it was added. None of them were audited against the others. On a traditional search stack, this sloppiness was mostly harmless — Google’s indexer has always been forgiving of duplicate or partially conflicting markup, silently picking a winner or ignoring the noise. Answer engines built for retrieval-augmented generation are not built with the same tolerance, because the cost of citing a wrong or unverifiable entity is reputational for the model provider, not just an indexing inconvenience.
How Schema Debt Actually Accumulates on WordPress
Enterprise WordPress stacks are rarely built by one team in one sitting. They are assembled over years, and every layer that gets added has its own opinion about what schema it should emit. The most common source of conflict is the coexistence of an SEO plugin — Yoast SEO or Rank Math being the two dominant candidates — with a theme framework that independently ships its own Organization, BreadcrumbList or Article markup. Premium enterprise themes frequently bake in structured data as a selling point (“built-in SEO schema”) without any awareness that a plugin further up the stack is already generating a competing graph. Both fire on page load. Both are technically valid JSON-LD. Neither knows the other exists.
A second, more insidious pattern appears during SEO plugin migrations. Moving from Yoast to Rank Math, or vice versa, is rarely a clean cutover. It is common for both plugins to remain active during a transition period — one deactivated in the admin UI but still leaving cached schema output in page builder templates, or both active simultaneously while a team evaluates which to keep. For weeks or months, the site emits two full schema graphs per page, each declaring its own WebSite and Organization entities with slightly different @id values, different sameAs arrays, sometimes different registered names if a rebrand happened mid-migration.
Page builders introduce a third failure mode. Elementor and its equivalents generally integrate well with the major SEO plugins for page-level meta and primary schema, but widget-level content — FAQ accordions, review blocks, pricing tables — is a blind spot. Because the builder doesn’t understand that a FAQ widget should emit FAQPage markup, technical teams often bolt on manual JSON-LD via a custom HTML widget or code snippet. That snippet is written once, by whoever was solving the immediate problem, with no reference to the @id conventions the SEO plugin is using elsewhere on the page. The result is an orphaned schema block: syntactically valid, contextually disconnected, and frequently duplicating an Organization reference that already exists elsewhere on the page under a different identifier.
The fourth and most persistent source is custom code. Someone, at some point, needed LocalBusiness markup for a specific service page and added a hardcoded JSON-LD snippet via a functions.php hook or a code injection plugin. That snippet was correct for its moment. It was never revisited when the SEO plugin was later configured to output its own LocalBusiness schema sitewide. Two years on, nobody remembers the manual snippet exists, and it silently conflicts with the plugin’s output on every page it was applied to.
What the Validators Actually Report — and What They Don’t
Google’s Rich Results Test and the Schema.org validator are the two tools most technical teams reach for, and they answer different questions. The Rich Results Test is scoped to rich result eligibility. When it encounters duplicate entities on a page, it will often flag that an Organization or a WebSite block “appears twice,” or that it cannot determine a primary entity, but its diagnostic depth stops at whatever affects Google’s own rich result eligibility. It is also worth knowing that the tool silently ignores comments inside JSON-LD blocks — not part of the JSON-LD spec, but common practice in hand-edited snippets — which means a developer’s inline annotation explaining why a block exists can mask the fact that the block itself is malformed or orphaned.
The Schema.org validator is the more useful instrument for this specific audit, because it is not trying to determine rich result eligibility — it is checking structural correctness against the vocabulary itself. It will surface improperly resolved @id references, missing required properties, and cases where the same identifier is used to describe two structurally different node types. Where the Rich Results Test tells you “this might not qualify for a carousel,” the Schema.org validator tells you “this graph does not parse to a single coherent set of entities.” For a schema debt audit, you need the second answer, not the first.
Neither tool, critically, tells you what an AI retrieval system does with the conflict. They are built for a different consumer. This is the gap technical teams consistently underestimate: passing the Rich Results Test with no errors does not mean the page presents an unambiguous entity to a language model performing retrieval. A page can be “valid” by Google’s rich-result standard while still containing two Organization nodes with different @id values, which is precisely the condition that causes an answer engine to discard the entity layer.
Why Retrieval Systems Discard Rather Than Reconcile
It helps to understand what an AI answer engine is doing mechanically when it encounters your page during retrieval. It is not rendering your site the way a browser does. It is parsing extracted content and any structured data alongside it, attempting to build a confident map of entities, attributes and relationships that it can cite without contradiction. When it finds two different Organization declarations claiming to be the same page’s operator — different registered names, different sameAs links, different @id anchors — it has encountered a contradiction it cannot safely resolve on its own. Resolving it would mean guessing which declaration is correct, and a well-behaved retrieval system is deliberately conservative about guessing when the outcome is a factual citation attached to a real business.
This conservatism is by design, not a limitation to be worked around. AI answer engines that hallucinate entity attribution create liability for the platform serving the answer, so the incentive structure favours silent omission over confident-but-wrong citation. The practical effect for you is that ambiguity doesn’t get resolved in your favour by default — it gets resolved by exclusion. This is consistent with the broader finding that malformed or orphaned structured data — broken nested @id nodes, contradictory node types — measurably reduces the probability that a page is used as a citation source, because the model treats structural incoherence as evidence of low trustworthiness in the source itself, not as a minor technical defect to look past.
There is a compounding effect worth naming here. Retrieval systems that synthesise a single answer from multiple candidate sources are, in effect, running a lightweight source-credibility ranking across everything they’ve retrieved. Structural trustworthiness — well-formed, internally consistent structured data — is one of the signals that feeds that ranking, alongside source authority, freshness, and corroboration across other pages. A page with clean, consolidated schema isn’t guaranteed a citation, but a page with contradictory schema is competing with a structural handicap that has nothing to do with the quality of its content.
The Correct Pattern: One @graph, Consistent @id Anchoring
The fix is architectural, not additive. Adding a third schema block to reconcile two conflicting ones only produces three sources of truth instead of two. The correct pattern consolidates all structured data for a given page into a single <script type="application/ld+json"> block using the @graph array, with every entity assigned a stable, canonical @id derived from the page’s canonical URL.
Practically, this means declaring your sitewide Organization and WebSite entities once, in a master schema block referenced consistently across the site, using @id values such as https://example.com/#organization and https://example.com/#website. Every page-level entity — a specific WebPage, an Article, a FAQPage — then references those established identifiers rather than redeclaring the organisation from scratch. A blog post’s schema should say “this page’s publisher is https://example.com/#organization,” not restate the organisation’s name, logo and sameAs array a second time with slightly different values.
The discipline that matters most here is @id consistency at the string level. If your canonical URLs sometimes resolve with a trailing slash and sometimes without, or your site has historically mixed www and non-www variants, your @id anchors will silently fracture across the site — two pages both trying to reference “the organisation” but pointing at two technically different identifier strings. This is a common, avoidable failure: lock the canonical URL pattern (protocol, host, trailing slash, case) before you standardise @id values, document it, and treat any deviation as a build failure rather than a cosmetic inconsistency.
Where possible, this consolidation should happen through the tooling you already have rather than by replacing it wholesale. Rank Math exposes a rank_math/json_ld filter specifically for extending its generated graph rather than overriding it; Yoast provides comparable hooks. The engineering discipline is to treat these filters as the single injection point for anything custom — a manually coded LocalBusiness node, a widget-level FAQPage block — rather than adding a parallel, disconnected <script> tag elsewhere in the template. If a theme’s built-in schema output cannot be filtered this way, it should be disabled outright, even if that requires a small custom snippet in functions.php, because a theme that cannot be made to defer to the canonical graph is a permanent source of debt.
Assigning Ownership Before You Assign Fixes
Most schema debt audits fail not at the technical level but at the governance level: nobody has been assigned ownership of any single entity type, so the fix gets applied once and regresses within a quarter. Before writing a line of consolidation code, inventory every plugin, theme, page builder, custom snippet and tag manager container capable of emitting JSON-LD on the site. For each schema type your site actually needs — Organization, WebSite, WebPage, Article, FAQPage, LocalBusiness, BreadcrumbList — assign exactly one owning source. Everything else is either disabled or explicitly treated as view-only and left unmodified.
This ownership map should live in version control alongside the code, not in a spreadsheet nobody reopens. A short internal document that states “Rank Math owns Organization, WebSite and Article; the FAQ widget owns FAQPage via a filtered extension of the Rank Math graph; the theme’s native schema output is disabled in functions.php” gives the next engineer who touches the stack — whether that’s your team in eighteen months or an external agency brought in for a redesign — a single point of reference instead of an archaeology exercise.
Catching Regressions Before They Reach Production
Schema debt rarely arrives as a single dramatic failure. It arrives incrementally, one plugin update, one theme change, one well-intentioned developer adding a snippet to solve an unrelated problem. The only durable defence is treating schema output as a build artefact subject to the same validation discipline as any other code, rather than something checked manually after the fact.
In practice, this means adding an automated linting step to your deployment pipeline that extracts every JSON-LD block from a representative set of page templates on a staging build and checks for the specific failure conditions that matter: duplicate @id values referring to different node content, Organization or WebSite nodes appearing more than once per page, and unresolved @id references that point to nothing in the graph. This does not need to be exhaustive schema validation against the full Schema.org vocabulary — that’s what the Schema.org validator is for during manual review — but it does need to run automatically on every deployment, failing the build or at minimum flagging the pull request when a regression is introduced. A staging environment check using the Rich Results Test and the Schema.org validator against a handful of representative URLs — home, a product or service page, a blog post, a location page if applicable — should be a standing item before any release that touches theme, plugin, or template code, not an occasional afterthought.
Auditing Debt at Scale Without Checking Every URL
For an enterprise site with hundreds of pages or multiple subdomains, manually pasting URLs into a validator does not scale and was never going to catch the systemic issue anyway — because schema debt is a template-level defect, not a page-level one. If your product template emits duplicate Organization nodes, every product page has the same defect, and auditing them individually only tells you what you already knew after the third page.
The correct approach is a headless crawl — Screaming Frog configured for custom JSON-LD extraction, or a purpose-built Node.js script, works equally well — that pulls every inline <script type="application/ld+json"> block across one representative URL per page template: home, category, product, blog post, location page, pricing page, and any bespoke landing page types. Rather than validating rich-result eligibility, the extraction should be parsed programmatically to flag exactly the conditions described above: multiple nodes of the same @type on one page, mismatched @id values referencing the same conceptual entity, and orphaned @id references. Run this against staging before every significant release, and periodically against production to catch drift introduced by content editors or third-party scripts that bypass your build pipeline entirely — tag manager containers being a common, overlooked source of exactly this kind of unmanaged JSON-LD injection.
This is verification of presence, not validation of correctness, and the two are not the same audit. Presence tells you the schema exists where you expect it. Validation — ideally run against a sampled subset through the Schema.org validator, since full-site automated validation against the vocabulary is rarely worth the engineering cost — tells you whether what exists actually resolves to one coherent entity. An enterprise audit needs both stages, and skipping the second is how technically “complete” schema coverage coexists with structural contradiction across an entire site.
The Takeaway
Schema debt is not a cosmetic markup problem you can defer. It is the difference between an AI answer engine treating your organisation as a single, verifiable entity it can cite with confidence, and treating your page as a source it cannot safely attribute anything to. The fix is not adding more schema — it is consolidating what already exists into one authoritative @graph, anchored by consistent @id values, owned by a single accountable source per entity type, and defended by automated validation in your deployment pipeline rather than manual spot-checks after launch. Enterprises that treat this as a one-off cleanup will regress within one plugin update cycle. Those that treat it as a governed, version-controlled architectural constraint will find their entity declarations still coherent long after the team that built them has moved on.
Frequently asked questions
What is schema debt?
Schema debt is the accumulation, across successive plugin installs, theme updates and migrations, of multiple JSON-LD blocks on the same URL that were each correct in isolation but were never audited against one another, leaving conflicting entity declarations on the page.
Why do AI answer engines discard pages with conflicting Organization schema instead of reconciling it?
A retrieval system that finds two different Organization or WebSite declarations claiming the same page has no safe way to guess which is correct, and because a wrong citation carries reputational risk for the model provider, the system defaults to silent omission rather than confident-but-wrong attribution.
How does schema debt typically build up on WordPress sites?
It accumulates through four common patterns: an SEO plugin and a theme framework each emitting competing schema, incomplete migrations between plugins like Yoast and Rank Math, orphaned JSON-LD bolted onto page builder widgets, and hardcoded custom code snippets that are never revisited once plugin-level schema changes.
Will passing Google’s Rich Results Test confirm my structured data is safe for AI retrieval?
No — the Rich Results Test only checks eligibility for Google’s rich results and can pass a page that still contains two Organization nodes with different @id values, which is precisely the condition that causes an AI answer engine to discard the entity layer; the Schema.org validator is the more relevant instrument for checking structural coherence.